Real-Time Analytics

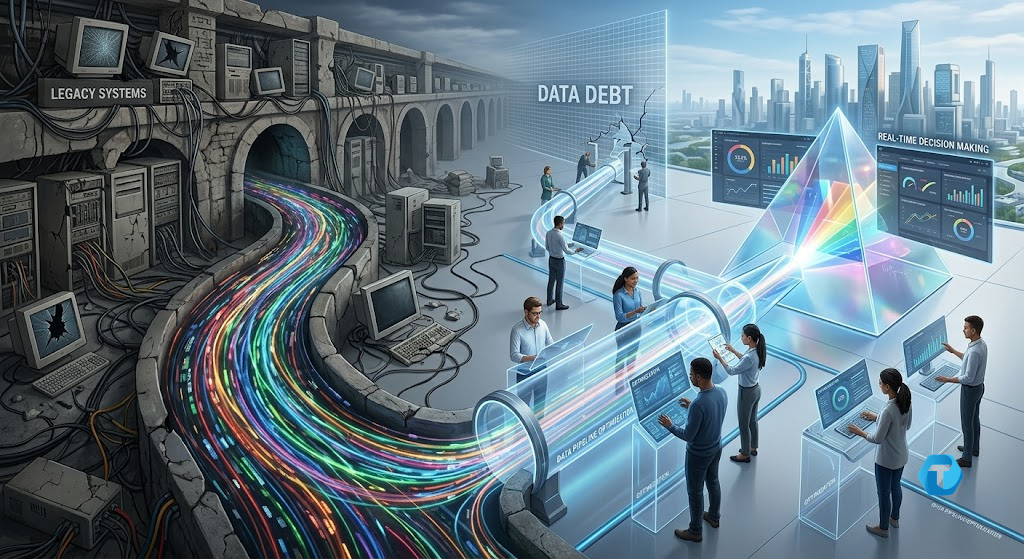
Data pipeline optimization and real-time data streaming architecture graphic
Technology & Innovation

Tackling Data Debt: A Strategic Blueprint for Data Pipeline Optimization and Real-Time Decision Making

Tackling Data Debt: A Strategic Blueprint for Data Pipeline Optimization and Real-Time Decision Making Every scaling enterprise eventually reaches a critical tipping point where its most valuable asset becomes its primary operational bottleneck. You see it in executive dashboards that take hours to refresh, cloud infrastructure invoices that balloon without explanation, and data engineering teams spending eighty percent of their week patching broken ETL scripts. This silent accumulation of architectural band-aids, shortcut queries, and unmonitored dependencies is what technical leaders call data debt. For Chief Data Officers, Lead Data Engineers, and BI Managers, data debt is not merely a backend inconvenience—it directly hampers your company’s ability to capitalize on fresh operational signals. When marketing needs immediate insights on campaign conversions, or risk management demands sub-second fraud detection, legacy batch infrastructure collapses under the pressure. Our team at Techotd frequently meets enterprise leaders whose analytics stacks were built for yesterday’s daily batch routines rather than today’s event-driven demands. Eliminating this structural drag requires a comprehensive strategy centered on data pipeline optimization—turning fragile, slow processing flows into resilient, low-latency pipelines that power confident, real-time decision making across the business. The Invisible Drag of Data Debt on Modern Engineering Teams Data debt rarely accumulates overnight during a single catastrophic project failure. Instead, it creeps into enterprise systems through dozens of everyday tactical compromises. A marketing team requests an urgent ad-hoc report, so a developer writes a quick SQL script directly against a production database. Six months later, four downstream dashboards and two financial reporting tools quietly depend on that unmonitored, undocumented script. Multiply this pattern across fifty departments and hundreds of microservices, and you inevitably end up with a tangled “spaghetti architecture” that nobody dares to touch. Historically, enterprise data infrastructure relied heavily on traditional night-time batch processing. Relational databases staged raw records, scheduled cron jobs executed heavy SQL transformations during off-peak hours, and pre-aggregated data marts served static morning reports. That model worked well when business operations moved at a daily or weekly rhythm. Today, however, business operations run continuously, and waiting twelve hours for updated inventory levels or user activity logs creates unacceptable competitive lag. When growing enterprises attempt to force legacy batch systems to support real-time demands without undertaking root-cause refactoring, several severe operational pain points surface: Pervasive Data Latency: Crucial business units are forced to make high-stakes choices using stale information. By the time supply chain anomalies, customer churn triggers, or transaction anomalies appear on executive dashboards, the opportunity to mitigate the issue has already passed. Runaway Cloud Infrastructure Costs: Unoptimized SQL transformations running on modern cloud data warehouses without proper partitioning, clustering, or materialization strategies burn through compute credits at an alarming rate. Schema Drift Instability: When upstream application teams modify database schemas without cross-team coordination, downstream pipelines fail silently. This introduces subtle errors into reporting layers and severely damages leadership’s trust in data accuracy. Engineering Fatigue and Turnover: Senior data engineers spend their time firefighting broken jobs, debugging fragile dependencies, and performing manual backfills instead of architecting innovative machine learning capabilities. A structured initiative focused on data pipeline optimization is the only sustainable path out of this cycle. By decoupling ingestion from heavy transformations and removing redundant computation paths, technical leaders can eliminate historical debt while establishing an agile, real-time analytics baseline. How It Works in Practice: Engineering a High-Throughput Real-Time Pipeline Transforming fragile legacy data flows into robust, continuous pipelines requires moving away from rigid, monolithic batch jobs toward an event-driven, decoupled processing model. When our architects at Techotd evaluate enterprise data platforms, we emphasize modularity, horizontal elasticity, and strict data contracts right at the point of ingestion. Here is how modern high-throughput architectures function in production: 1. Event-Driven Ingestion and Change Data Capture (CDC) Rather than executing resource-intensive polling queries against production transactional databases every night, modern architectures capture record changes in near-real-time. Using  and distributed streaming platforms like Apache Kafka or Redpanda, operational events—such as a completed order or an updated customer profile—are published to dedicated stream topics the moment they occur. This eliminates heavy database locks on operational systems while capturing precise audit histories. 2. Stream Processing and In-Memory Transformations As events flow into the streaming broker, distributed engines like Apache Flink or Spark Streaming transform, validate, and enrich the data on the fly. Instead of landing raw data into storage and running heavy SQL queries later, stream processors compute running aggregates—such as rolling ten-minute transaction totals or dynamic risk scoring—with sub-second latency. 3. Decoupled Storage and Materialization Layers Storage strategies must reflect how downstream applications consume information. Key-value lookups for operational applications should land in ultra-fast caches like Redis or DynamoDB, whereas long-term analytical trends belong in columnar lakehouse storage like Snowflake, BigQuery, or Databricks. Effective data pipeline optimization ensures data is converted into efficient columnar formats like Apache Parquet or Iceberg before hitting storage layers. 4. Idempotency and Pipeline Observability Continuous pipelines must tolerate network blips, late-arriving events, and schema changes without crashing. Building pipelines for idempotency guarantees that processing the exact same event multiple times yields identical final states. Furthermore, incorporating automated data observability into your data pipeline optimization strategy allows engineering teams to track end-to-end data lineage, detect schema drift instantly, and flag quality anomalies before they impact business users. +————————–+ | Operational Databases | +————————–+ | v (CDC / Debezium) +————————–+ | Apache Kafka Topics | +————————–+ | v +————————–+ | Apache Flink Stream Ops | +————————–+ | +——+——+ | | v v +———–+ +————+ | In-Mem | | Columnar | | Cache | | Lakehouse | +———–+ +————+ Strategic Impact & Measurable Value for Executive Leaders Refactoring your core data infrastructure is far more than a technical housekeeping project; it directly transforms enterprise operational economics and market agility. For Chief Data Officers and BI Managers, investing in systematic data pipeline optimization converts back-office engineering improvements into direct financial savings and strategic advantages. Consider the tangible executive value achieved through modernized pipeline architectures: Significant Infrastructure Spend Reduction: By eliminating duplicate data processing routes, optimizing query execution logic,
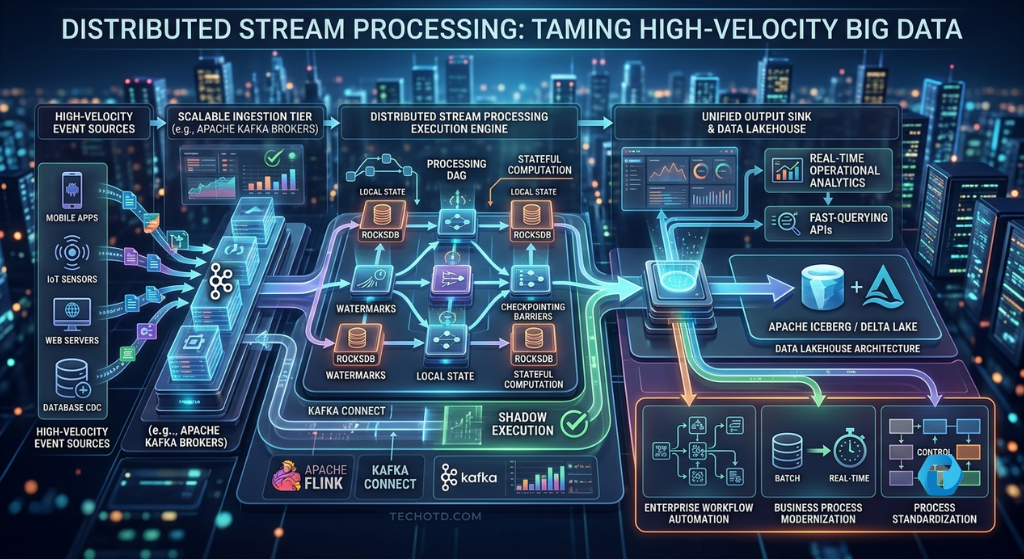
Distributed Stream Processing Architecture Diagram with Kafka and Flink
Big Data

Distributed Stream Processing Architectures: Taming High-Velocity Big Data Streams

In modern enterprise data environments, the traditional paradigm of nightly batch processing is rapidly becoming an operational liability. As business domains demand instantaneous decision-making—ranging from high-frequency fraud detection in financial clearinghouses to predictive telemetry in autonomous IoT fleets—data must be computed continuously at the moment of creation. Implementing distributed stream processing allows organizations to transition from passive historical reporting to proactive, low-latency execution engines operating on continuous data streams. Part 1: The Paradigm Shift from Batch Decoupling to Continuous Streams Historically, enterprise data architectures relied on monolithic Extract, Transform, Load (ETL) pipelines that executed on scheduled intervals. While batch systems like MapReduce or traditional SQL data warehouses served historical analytics well, they introduced a structural latency window ranging from hours to days. In high-velocity environments, this temporal delay dilutes the operational value of telemetry data. According to market intelligence from International Data Corporation (IDC), over 30% of global data generated across connected networks is real-time in nature. Furthermore, financial sector benchmark studies demonstrate that credit card fraud detection models lose up to 70% of their predictive utility if analytical scoring exceeds a 200-millisecond window. The core challenge of Big Data is no longer merely managing massive volume; it is solving for extreme velocity without compromising transactional correctness. Transitioning from static datasets to continuous event streams requires moving away from disk-bound tabular storage toward append-only log primitives. Rather than querying state that sits at rest, distributed stream processing flips the computing paradigm: queries remain persistent and long-running within memory while unbounded data flows continuously through them. Part 2: The Core Anatomy of Distributed Stream Processing To process millions of incoming events per second with sub-second response times, streaming platforms decouple ingestion, compute, and state management into specialized distributed tiers. At the ingestion boundaries, high-throughput partitioned message logs—such as Apache Kafka or Apache Pulsar—serve as the durable event bus. These brokers utilize sequential append-only disk writes to achieve multi-gigabyte ingestion speeds while providing deterministic offset management for message replays. Directly downstream sits the execution engine. Modern distributed stream processing engines utilize Directed Acyclic Graph (DAG) query planners to distribute partition-level workloads across worker clusters. Unlike stateless microservices, streaming compute nodes maintain local physical state in high-performance key-value stores (such as RocksDB embedded directly within host memory). By retaining local state buffers, stream engines eliminate the network round-trip overhead traditionally incurred when querying remote databases during event enrichment. This enables stateful compute operations—such as sliding temporal aggregations, multi-stream joins, and sessionization—to execute with microsecond locality. Part 3: Overcoming Latency, Out-of-Order Events, and State Consistency Operating a continuous compute engine across non-deterministic distributed networks presents severe architectural trade-offs, specifically regarding time domains, network jitter, and node failures. 1. Disentangling Event Time from Processing Time In distributed networks, the moment an event occurs in the physical world (Event Time) rarely aligns perfectly with the moment it arrives at the processing server (Processing Time). Network latency, device disconnects, and mobile queue backups cause messages to arrive out of order. Advanced distributed stream processing frameworks resolve this by utilizing watermarks—heuristic markers embedded into the stream stream that signal temporal completeness. Watermarks allow stateful windows to progress deterministically based on event timestamps rather than volatile wall-clock server times. 2. Guaranteeing Exactly-Once Processing Semantics In the event of hardware failures or worker crashes, stream processing systems must recover state without dropping events (at-most-once failure) or duplicating calculations (at-least-once failure). Achieving true exactly-once semantics (EOS) requires two structural synchronization mechanisms: Asynchronous Barrier Checkpointing: Based on variants of the Chandy-Lamport algorithm, lightweight snapshot barriers flow alongside data records through the DAG, persisting execution state to durable object storage without blocking pipeline throughput. Two-Phase Commit (2PC) Sink Operators: Ensuring that state writes to external sinks (such as transactional databases or storage layers) commit synchronously with the engine’s internal checkpoint offsets. Part 4: Architectural Blueprint: Integrating Kafka, Flink, and the Data Lakehouse Building a enterprise-grade real-time analytical ecosystem requires orchestrating message brokers, stream processors, and unified storage formats into a cohesive topology. A battle-tested production blueprint structures data flow across four decoupled layers: Ingestion Tier: Edge telemetry, application logs, and database Change Data Capture (CDC) streams are published to partitioned topics in Apache Kafka. Stream Processing Tier: Distributed engines like Apache Flink or Spark Structured Streaming consume topic partitions, applying windowed transformations, machine learning inference models, and real-time alerts. Speed Layer Storage: Low-latency key-value stores (such as Redis or Apache Cassandra) store the immediate results of streaming aggregations for real-time dashboarding and API querying. Unified Storage Tier: Stream sinks flush immutably transformed event logs into open table formats like Apache Iceberg or Delta Lake. This unifies streaming and batch analytics under a cohesive Data Lakehouse architecture. By deploying this decoupled topology, enterprise data teams eliminate brittle point-to-point integrations and establish a unified streaming backbone capable of serving both operational applications and offline machine learning pipelines. Key Takeaways for Distributed Stream Processing Unlocking real-time intelligence requires moving beyond ad-hoc data pipelines toward disciplined architectural patterns. Adopting scalable distributed stream processing allows engineering organizations to process unbounded event streams with mathematical correctness, guaranteeing state consistency despite cluster failures. By coupling stateful streaming compute with open table storage formats, enterprises can systematically eliminate operational latency, reduce infrastructure overhead, and drive automated decision systems at scale. Frequently Asked Questions (FAQ) What is the difference between batch processing and distributed stream processing? Batch processing executes queries on bounded, historical datasets stored at rest on fixed time schedules. In contrast, distributed stream processing executes long-running, continuous queries over unbounded event data in motion, delivering low-latency results within milliseconds of event generation. How do stateful stream processors maintain recovery during node failures? Stateful stream engines maintain internal state locally in high-performance embedded key-value stores (e.g., RocksDB) while periodically taking distributed, non-blocking snapshots using checkpoint algorithms. If a worker node crashes, the system recovers state by resetting execution offsets to the latest valid checkpoint and replaying subsequent message logs. Why is event time critical in real-time streaming pipelines? Event time reflects the exact epoch timestamp when an action occurred at

Business Intelligence dashboard visualizing big data analytics trends
Business Intelligence

Big Data Analytics and Business Intelligence: Turning Information into Insight

Introduction In today’s hyper-connected digital world, data is the new oil — a powerful asset that drives innovation, strategy, and growth. Every second, billions of data points are generated from online transactions, social media, IoT devices, and business operations. But raw data is meaningless unless it’s analyzed, interpreted, and used to make informed decisions. That’s where Big Data Analytics and Business Intelligence (BI) come into play. Together, they empower organizations to uncover hidden trends, improve efficiency, and gain a competitive edge in the marketplace. What Is Big Data Analytics? Big Data Analytics is the process of examining large, complex datasets to discover hidden patterns, correlations, market trends, and customer preferences. Unlike traditional data analysis, Big Data Analytics can handle massive volumes (terabytes or petabytes) of structured and unstructured data at lightning speed.  The 5 Vs of Big Data: Volume – Massive amount of data generated daily Velocity – Speed at which data is created and processed Variety – Different formats (text, images, videos, logs, etc.) Veracity – Accuracy and reliability of data Value – Insights gained from analysis By leveraging technologies like Hadoop, Spark, and NoSQL databases, businesses can process and analyze enormous data efficiently. What Is Business Intelligence (BI)? Business Intelligence is a technology-driven process for analyzing data and presenting actionable insights to help executives, managers, and employees make informed business decisions. BI systems typically use dashboards, reports, and visualization tools like: Power BI Tableau QlikView Google Data Studio BI tools collect data from multiple sources, integrate it, and display results through interactive visual dashboards, making insights accessible to everyone. Big Data Analytics vs. Business Intelligence Aspect Big Data Analytics Business Intelligence (BI) Purpose Predict future outcomes Analyze past & present performance Data Type Structured + Unstructured Mostly structured data Tech Used Hadoop, Spark, Machine Learning Power BI, Tableau, SQL Output Predictive & prescriptive insights Descriptive & diagnostic insights Focus Exploration & forecasting Reporting & visualization In short, Big Data Analytics predicts what’s coming next, while Business Intelligence explains what’s happening now. Together, they create a 360° view of the organization, enhancing data-driven strategies. How Big Data and BI Work Together When integrated, Big Data and BI enable organizations to: Collect vast amounts of real-time data Process and store it efficiently Visualize complex patterns Support strategic business decisions Example:A retail company can use Big Data Analytics to predict customer purchase trends and then use BI dashboards to visualize which products are performing best in real-time. Key Components of Big Data and BI Ecosystem 1. Data Collection Data is gathered from multiple sources — sensors, CRM systems, web logs, transactions, and social media. 2. Data Storage Tools like Hadoop Distributed File System (HDFS), Amazon S3, or Google Cloud Storage store massive data volumes securely. 3. Data Processing Frameworks such as Apache Spark and Flink process the data for analysis. 4. Data Analysis Machine learning algorithms and statistical models identify patterns and trends. 5. Data Visualization BI tools like Power BI or Tableau present the results in interactive dashboards and graphs. Applications of Big Data and BI in Industries  1. Retail & E-Commerce Personalized product recommendations Dynamic pricing based on demand Customer behavior tracking Example:Amazon uses predictive analytics to recommend products, improving sales and customer engagement.  2. Healthcare Predictive diagnosis and treatment plans Disease outbreak tracking Patient data management Example:Hospitals use BI tools to monitor patient recovery and resource allocation. 3. Finance Fraud detection using real-time analytics Credit risk assessment Algorithmic trading Example:Banks use Big Data to identify suspicious transactions within seconds. 4. Manufacturing Predictive maintenance of equipment Supply chain optimization Quality control automation 5. Education Performance analytics for students Personalized learning paths Data-driven decision-making in administration Emerging Trends in Big Data and BI Artificial Intelligence Integration:Machine learning models now automate insights generation. Real-Time Analytics:Instant decision-making with live data streaming. Data Democratization:BI tools make analytics accessible to non-technical users. Augmented Analytics:Combines AI and natural language processing (NLP) for smarter reports. Edge Analytics:Data processing closer to the source for faster outcomes. Data Governance and Privacy:Ensuring compliance with regulations like GDPR and HIPAA. Benefits of Big Data Analytics and BI Benefit Impact Informed Decision-Making Data-backed strategic planning Cost Optimization Identify inefficiencies Customer Insights Understand preferences & behaviors Predictive Capabilities Anticipate future trends Competitive Advantage Gain market leadership Operational Efficiency Automate and streamline workflows Challenges in Big Data and BI Implementation Data quality and integration issues High storage and processing costs Security and privacy risks Shortage of skilled data professionals Over-dependence on tools without clear strategy However, with cloud-based solutions and AI-powered platforms, these challenges are becoming easier to overcome. Conclusion In the digital era, data is the foundation of success — but only when it’s analyzed effectively. Big Data Analytics gives organizations predictive power, while Business Intelligence delivers clarity and visibility. Together, they transform information into strategic insight, fueling smarter, faster, and data-driven decision-making. Companies embracing this synergy are not just surviving — they’re leading the future of business innovation. FAQs 1. What is the main difference between Big Data Analytics and Business Intelligence?Big Data focuses on analyzing large datasets for predictive insights, while BI focuses on reporting and visualizing historical data. 2. Why are Big Data and BI important?They help businesses make informed decisions, improve efficiency, and predict market trends. 3. What tools are used in Big Data Analytics?Hadoop, Spark, Hive, and Flink are commonly used tools. 4. What are popular BI tools?Power BI, Tableau, QlikView, and Google Data Studio are top BI tools. 5. What skills are needed for Big Data and BI?Data analysis, SQL, Python, visualization tools, and knowledge of databases.

Data analytics dashboard displaying visual graphs and metrics for business performance.
Big Data

Big Data Analytics: Powering Smarter Decisions in the Digital Age

Introduction In the modern world, data is often referred to as the “new oil” — a resource that drives innovation, business growth, and strategic decision-making. However, unlike oil, data’s value depends on how effectively it is analyzed and interpreted. This is where Big Data Analytics comes into play. From personalized recommendations on Netflix to predictive maintenance in manufacturing, Big Data has transformed the way organizations operate. By turning massive volumes of raw data into actionable insights, companies can make faster, smarter, and more confident decisions. In this blog, we’ll explore what Big Data Analytics is, its key components, real-world applications, benefits, challenges, and the future trends shaping this powerful field. What is Big Data Analytics? Big Data Analytics is the process of examining large and complex data sets — often too vast for traditional processing systems — to uncover hidden patterns, correlations, trends, and insights. It involves using advanced technologies like machine learning, artificial intelligence (AI), cloud computing, and data visualization to make sense of massive data generated every second. The 5Vs of Big Data: Volume: The huge amount of data generated from sources like social media, IoT devices, and transactions. Velocity: The speed at which new data is created and needs to be processed. Variety: The different formats of data — structured, semi-structured, and unstructured. Veracity: The reliability and accuracy of data. Value: The insights and business impact derived from analyzing the data. Types of Big Data Analytics Descriptive Analytics: Answers “What happened?” by summarizing historical data (e.g., monthly sales reports). Diagnostic Analytics: Answers “Why did it happen?” by identifying causes and relationships. Predictive Analytics: Answers “What might happen?” using statistical models and forecasting. Prescriptive Analytics: Answers “What should we do next?” by recommending actions based on predictive insights. Together, these analytics types empower organizations to move from hindsight to foresight, enabling smarter business strategies. How Big Data Analytics Works The process involves several key steps: Data Collection: Gathering data from sources such as IoT devices, social media, transactions, and sensors. Data Storage: Using platforms like Hadoop, Apache Spark, or cloud databases to store massive datasets. Data Processing: Cleaning and transforming raw data into usable formats. Data Analysis: Applying algorithms and tools like Python, R, or Power BI to extract insights. Visualization: Presenting data through dashboards and reports to support decision-making. Real-World Applications of Big Data Analytics 1. Healthcare Hospitals and research institutions use Big Data to predict disease outbreaks, personalize treatment plans, and improve patient care.Example: Analyzing patient histories and genetics helps doctors prescribe customized medicines for better outcomes. 2. Retail Retail giants like Amazon and Walmart use analytics to track customer preferences, optimize inventory, and personalize shopping experiences.Example: Big Data predicts buying behavior, allowing targeted ads and product recommendations. 3. Finance Banks and financial institutions use Big Data to detect fraud, assess credit risk, and enhance customer engagement.Example: Real-time fraud detection systems analyze thousands of transactions per second to flag anomalies. 4. Manufacturing Predictive analytics helps manufacturers forecast equipment failures and perform maintenance before breakdowns occur.Example: GE uses Big Data in its “Industrial Internet” to monitor and optimize production equipment globally. 5. Transportation Public and private transport companies analyze data from GPS, sensors, and ticketing systems to improve route efficiency and reduce congestion.Example: Uber uses real-time analytics to match drivers with passengers and set dynamic pricing. 6. Education Educational institutions use data analytics to track student performance, improve learning outcomes, and design adaptive learning programs. Benefits of Big Data Analytics Better Decision-Making: Real-time insights support quick and accurate strategic choices. Operational Efficiency: Identifies inefficiencies and optimizes workflows. Enhanced Customer Experience: Personalizes services based on data-driven behavior analysis. Fraud Detection: Monitors unusual activities and reduces financial risks. Innovation and Competitive Edge: Uncovers new opportunities and emerging market trends. Challenges in Big Data Analytics Data Privacy and Security: Managing sensitive information securely is a major concern. Data Quality Issues: Incomplete or inaccurate data leads to misleading insights. Integration Difficulties: Combining data from multiple systems and formats can be complex. Skill Gaps: There’s a shortage of skilled data analysts and data scientists. Infrastructure Costs: Building and maintaining large-scale data systems can be expensive. Emerging Technologies Shaping the Future of Big Data 1. Artificial Intelligence (AI) and Machine Learning AI automates data processing and enables predictive modeling with higher accuracy. 2. Edge Computing Brings data processing closer to the data source, reducing latency and bandwidth usage. 3. Cloud Analytics Cloud-based solutions make Big Data Analytics more scalable and accessible for businesses of all sizes. 4. Real-Time Analytics Organizations can now act instantly on insights — from fraud detection to dynamic pricing. 5. Data Fabric and Integration Platforms These unify disparate data sources, enabling seamless data sharing across departments. Big Data and Ethics As organizations handle massive amounts of user data, ethical considerations become essential. Businesses must ensure transparency, consent, and fairness in how they collect and analyze data. Implementing strong data governance frameworks and adhering to privacy laws like GDPR and CCPA are vital to maintaining public trust. Conclusion Big Data Analytics is revolutionizing industries, empowering organizations to make data-driven decisions that lead to innovation, efficiency, and growth. As AI, machine learning, and cloud technologies evolve, data analytics will become even more intelligent and accessible. However, success lies in balancing technology with ethical responsibility, ensuring that the power of data serves humanity positively. In the coming years, companies that embrace Big Data Analytics will not just predict the future — they’ll help create it. FAQs 1. What is Big Data Analytics used for? It’s used to analyze large datasets to uncover insights, trends, and patterns that help organizations make better decisions. 2. Which industries use Big Data Analytics the most? Healthcare, finance, retail, manufacturing, and transportation are leading sectors using Big Data for innovation and optimization. 3. How does Big Data improve business performance? It helps companies understand customer behavior, reduce costs, detect fraud, and predict future trends for better strategic planning. 4. What are the main tools for Big Data Analytics? Popular tools include Apache Hadoop, Spark, Tableau, Power

Digital business dashboard showing real-time analytics and performance metrics.
Real-Time Visibility

Real-Time Visibility: The Key to Smarter, Faster, and More Informed Decisions

Introduction In today’s fast-moving digital world, every second counts. Businesses can no longer afford to wait hours—or even minutes—for updates on critical operations. Real-time visibility has become a necessity, not a luxury. It provides instant access to live data, helping organizations monitor, track, and make better decisions at every level. What is Real-Time Visibility? Real-time visibility refers to the ability to view and analyze live data from systems, devices, or processes as it happens. It enables decision-makers to instantly understand what’s occurring within their business—whether it’s tracking shipments, monitoring network performance, or observing production efficiency. In simple terms, it’s about knowing what’s happening right now, not just what happened an hour ago. Why Real-Time Visibility Matters Instant Decision-Making:With immediate data access, businesses can respond faster to changes, disruptions, or risks. Operational Efficiency:Real-time monitoring helps identify inefficiencies quickly, allowing teams to act before issues escalate. Enhanced Customer Experience:Companies can provide accurate delivery times, proactive updates, and faster problem resolution. Cost Savings:By preventing errors and optimizing operations, organizations save time, money, and resources. Key Industries Using Real-Time Visibility 1. Supply Chain & Logistics Real-time tracking of shipments through IoT sensors and GPS. Instant alerts on route delays or temperature fluctuations in perishable goods. Improved coordination between suppliers, distributors, and retailers. 2. Manufacturing Monitoring production lines to detect machine failures instantly. Real-time quality control through automated systems. Optimized inventory management by tracking stock levels in real time. 3. Healthcare Live monitoring of patients’ vitals. Real-time updates on medication administration and equipment usage. Faster response to emergencies through connected healthcare systems. 4. Information Technology Real-time visibility into network performance and cybersecurity threats. Instant system health checks and uptime monitoring. Quick detection of server or application issues. Technologies Behind Real-Time Visibility Internet of Things (IoT): Enables sensors and devices to share live data. Cloud Computing: Allows real-time data processing and storage accessible anywhere. Artificial Intelligence (AI) & Machine Learning (ML): Automates analysis of large datasets instantly. Blockchain: Provides transparent, tamper-proof data sharing. Data Dashboards & Analytics Tools: Help visualize live insights for faster action. Benefits of Implementing Real-Time Visibility Benefit Impact Faster response to disruptions Reduced downtime and better service delivery Improved forecasting Data-driven planning and decision-making Transparency Builds trust with customers and stakeholders Compliance Easier tracking and audit readiness Challenges in Achieving Real-Time Visibility While the benefits are clear, implementing real-time visibility comes with challenges: Data Overload: Managing huge volumes of live data can be complex. Integration Issues: Connecting multiple systems and platforms seamlessly. Security Concerns: Protecting sensitive real-time data from cyber threats. High Initial Costs: Investment in technology and infrastructure. Future of Real-Time Visibility The future is intelligent and connected. With advancements in AI-driven analytics, 5G networks, and edge computing, real-time visibility will become faster and more accurate. Businesses that embrace it will gain a competitive edge by turning instant insights into powerful actions. Conclusion In a world where speed and accuracy define success, real-time visibility stands as a game changer. Whether in logistics, healthcare, IT, or manufacturing, it enables organizations to stay proactive, informed, and agile. Embracing this technology today means being prepared for the challenges of tomorrow. Frequently Asked Questions (FAQs)   1. What does real-time visibility mean? Answer: Real-time visibility refers to the ability to access and monitor live data from systems, devices, or business operations as it happens. It helps organizations make instant decisions, detect issues early, and improve efficiency. 2. Why is real-time visibility important for businesses? Answer: It enables companies to act proactively instead of reactively. With real-time data, businesses can identify bottlenecks, optimize performance, improve customer experience, and reduce costs. 3. Which industries benefit most from real-time visibility? Answer: Industries such as supply chain and logistics, manufacturing, healthcare, retail, and IT operations benefit greatly from real-time visibility. It allows them to track assets, monitor systems, and respond to issues instantly. 4. What technologies enable real-time visibility? Answer: Technologies like IoT (Internet of Things), cloud computing, AI and machine learning, blockchain, and real-time analytics dashboards are key enablers of real-time visibility systems. 5. What are the main challenges in implementing real-time visibility? Answer: The primary challenges include data overload, integration of multiple systems, data security concerns, and high initial setup costs for technology infrastructure. 6. How does real-time visibility improve customer satisfaction? Answer: By providing live updates, accurate tracking, and quick responses, businesses can enhance transparency and build trust with their customers—leading to higher satisfaction and loyalty. 7. What is the future of real-time visibility? Answer: With advancements in 5G, AI-driven analytics, and edge computing, the future of real-time visibility will be even faster, smarter, and more integrated across global systems.

2D illustration of a modern bank with professionals examining colorful digital analytics dashboards, security icons, and vibrant graphs, highlighting data analytics in banking.
data science

Data Analytics in Banking: Transforming Finance in 2025

  Introduction The banking industry is entering a new era—where every transaction, service, and decision is powered by data analytics in banking, banking analytics, and data-driven banking. From retail and commercial banking to investment and treasury, financial institutions are now harnessing the power of analytics tools, financial data analysis, and artificial intelligence to drive smarter strategies, deliver personalized customer experiences, prevent fraud, and manage risk more effectively than ever before. In today’s competitive financial landscape, banks that embrace data analytics not only thrive—they set the pace. For insights on related financial innovation, read our guide to predictive analytics software development. For the latest industry research from a leading consultancy, visit McKinsey Financial Services Insights. How Data Analytics Powers Modern Banking Fraud Detection and AML/KYC Real-time transaction monitoring, anomaly detection, and predictive analytics flag suspicious activity for strong anti-fraud and compliance measures in banking analytics. Machine learning models analyze transaction patterns to detect fraud, building trust and reducing losses for data-driven banking. Customer Segmentation & Personalization Banks group customers by behavior, demographics, and spending patterns for highly relevant product offerings powered by financial data analysis. Personalized recommendations, communications, and experiences increase retention by up to 85% when personalization is prioritized in data analytics in banking. Credit Risk Assessment Advanced credit analytics leverage alternative data and predictive analytics models to accurately assess borrower risk, reducing non-performing assets. Faster and fairer data-driven lending decisions empower responsible lending and expand financial inclusion. Churn Prediction & Retention Analytics identify at-risk customers early, enabling banks to trigger proactive retention campaigns and reduce churn in banking analytics. Early intervention through data-driven banking strategies boosts long-term relationship value. Operational Efficiency & Compliance Streamlined reporting and process automation lower regulatory costs and compliance errors in banking analytics (compliance costs can drop by 20%). Automated pipelines support real-time reporting for Basel, IFRS9, and SEBI requirements with predictive analytics in banking. Predictive Analytics for Strategy Predictive analytics models anticipate cash/ATM demand, optimize pricing, assess investment risk, and forecast market trends for smarter business decisions. Scenario analysis enables banks to adapt to changing economic conditions using data analytics in banking. Real-World Use Cases   Use Case Description Fraud Detection Real-time analytics spot and prevent suspicious transactions using banking analytics. Personalized Banking Banks offer tailored products and services brought by data-driven banking and customer financial data analysis. Loan Default Prediction Machine learning credit scoring supports risk decisions, reducing losses in banking analytics. Compliance Reporting Automation cuts regulatory costs and errors in financial data analysis. Customer Churn Prediction Analytics identify at-risk accounts for targeted retention using predictive analytics. Pricing Optimization Data-driven interest rates and dynamic product pricing improve growth. Strategic ATM Placement Analytics and data-driven banking determine ATM locations for higher usage and savings. Benefits of Data Analytics in Banking Smarter, faster data-driven decisions for revenue growth Stronger fraud prevention and security through predictive analytics Better risk management using banking analytics tools Personalized customer engagement and loyalty Reduced operational costs and improved compliance in financial data analysis Deeper customer insight for strategic data-driven banking innovation Conclusion Data analytics in banking, banking analytics, and predictive analytics are transforming every facet of the industry—empowering institutions to innovate, mitigate risk, and deliver exceptional service. As financial data analysis and data-driven banking become standard in 2025, analytics will drive resilient, future-ready financial strategies. FAQ How does data analytics prevent banking fraud? By using real-time monitoring and machine learning, analytics detect fraudulent patterns and anomalies rapidly, minimizing losses. What is customer segmentation and why does it matter? It’s grouping customers by behavioral and demographic traits, helping banks target relevant offerings for higher engagement and loyalty. How does analytics improve loan approval speed? Credit scoring models use multiple data sources for instant, accurate risk assessment—approving loans faster and reducing bad debt. Can analytics reduce compliance costs? Yes, automation of reporting and data management slashes compliance expenses and error rates. What’s the future of analytics in banking? Expect smarter AI models, blockchain integration for data transparency, real-time insights, and hyper-personalized banking as standard.  

Feature image showing customer data platform (CDP) benefits for retail businesses, with colorful data analytics visuals and modern retail store elements.
Software development

10 Reasons You Need a CDP for Your Retail Business

  Introduction In today’s data-driven retail landscape, understanding and connecting with customers is crucial to success. Modern retailers rely on advanced software solutions like a Customer Data Platform (CDP) to unify fragmented customer data into a single hub. This empowers retail technology ecosystems to create personalized experiences, optimize marketing, and boost sales. As machine learning retail analytics, privacy regulations, and digital channels expand, a robust e-commerce CDP is no longer a luxury—it’s an essential tool for thriving in retail. This blog explores ten powerful reasons every retailer needs a CDP and offers actionable steps to build one, with deep insights and internal links to TechOTD’s leading resources. 10 Reasons You Need a CDP for Your Retail Business 10 Reasons Your Retail Business Needs a CDP 1. Unified Customer View A CDP creates a single, comprehensive profile for each customer by consolidating data from online stores, point-of-sale systems, mobile apps, and loyalty programs. This unified profile becomes the backbone of your retail system, supporting better understanding and improved decision-making. 2. Improved Personalization With unified data, retailers can deliver highly personalized product recommendations, emails, and offers. Personalization increases engagement and conversion rates by leveraging smart machine learning retail models within your CDP. 3. Enhanced Customer Segmentation CDPs enable segmentation based on behaviors, demographics, and purchase history—so messaging and offers are always relevant to each group, making your retail technology strategy more powerful. 4. Better Marketing ROI Precise targeting with real-time data means fewer wasted ad dollars and more effective campaigns. CDPs boost return on ad spend (ROAS) and improve overall marketing efficiency using advanced software analytics. 5. Seamless Omnichannel Experience CDPs unify customer journeys across web, apps, email, and physical stores, ensuring consistent messaging and experiences no matter where customers interact—essential for any e-commerce cdp implementation. 6. Data Compliance and Privacy Managing customer data centrally makes compliance with GDPR, CCPA, and other privacy regulations easier, reducing legal risks. 7. Real-Time Analytics and Insights Advanced analytics allow retailers to track campaign performance, predict churn, and uncover trends for smart, agile decision-making within your retail system. 8. Recover Abandoned Carts CDPs enable personalized follow-up emails and offers that re-engage customers and recover lost sales—using software-powered triggers for timely communication. 9. Customer Retention and Loyalty By understanding and responding to customer needs, CDPs empower loyalty programs and incentives, driving repeat purchases and long-term relationships with the help of advanced retail technology. 10. Marketing Automation and Efficiency Automated workflows triggered by customer actions save time, increase relevance, and let teams focus on strategy instead of manual tasks. This is the essence of modern retail software. How to Build a CDP for Your Retail Business Building a CDP is a strategic process that ensures your investment aligns with business goals—and delivers ongoing value for your retail system. 1. Assess Your Business Needs Identify whether you want more personalization, improved retention, or seamless omnichannel experiences. Clear goals inform every subsequent step. 2. Audit Existing Data Sources Review all systems with customer data (e.g., CRM, online store, loyalty programs—a part of your retail system), identify overlaps and gaps, and clean your data to ensure reliability. 3. Design the Architecture Plan how the CDP will connect to platforms like CRMs, e-commerce, POS, and marketing tools—key elements of retail technology. Define rules for real-time and batch data processing, access control, and regulatory compliance. 4. Develop and Integrate the Platform Choose scalable technology and APIs to bridge systems, ensure rapid data sync, and prioritize security. Integrate with existing processes and future-proof for business expansion using suitable software. 5. Define Segments and Attributes Map out key customer attributes and create segments for targeted campaigns (e.g., VIPs, frequent buyers, at-risk customers). 6. Personalization and Automation Configure real-time triggers for personalized messages, recommendations, and offers using machine learning retail tools. Use automation tools to deliver the right communication at the right time. 7. Privacy and Compliance Management Build in privacy controls and consent management. Keep customer trust by being transparent about data handling and honoring customer choices. 8. Measure and Optimize Set clear KPIs, monitor campaign results, and adjust segments, messages, and strategies using live data and advanced analytics software. Key Points Table Reason/Step Description Unified Customer View Single profile per customer enables better understanding and interactions. Improved Personalization Data-driven product recommendations and offers for each user. Enhanced Segmentation Group customers for relevant messages and campaigns. Marketing ROI Fewer wasted ads, real-time performance tracking, higher sales. Omnichannel Experience One smooth journey across online and offline touchpoints. Compliance & Privacy Centralized data simplifies consent management and data regulations. Real-Time Analytics Track trends, campaign success, and customer needs as they happen. Recover Carts Use behavioral data to re-engage and convert lost customers. Retention & Loyalty Data-driven incentives for long-term relationships and repeat sales. Automation Hands-off, triggered messaging and campaigns improve efficiency. For insights on how AI and software are transforming retail, read our guide on Machine Learning in Healthcare for parallels in data-driven innovation: Machine Learning in Healthcare Explore the future of AI-powered customer service in retail technology with our article on Seamless Customer Journeys with AI: Seamless Customer Journeys with AI – The Future of Service Excellence Understand how predictive analytics software enhance CDP capabilities in retail by visiting: Predictive Analytics Software Development – Features, Benefits, Use Cases, Process, and Cost Discover how cloud technology supports modern retail systems in our comprehensive guide: Cloud Computing – An Ultimate Guide for Businesses Learn about agentic RAG and its applications for smarter data management in retail systems: Agentic RAG: What It Is, Types, Applications, and Implementation Read about confidential AI systems transforming data security and compliance in retail technology: Confidential AI Conclusion A Customer Data Platform is a must-have software for every modern retail business. By connecting disparate data sources, enabling true omnichannel engagement, and powering personalization through machine learning retail analytics, a CDP puts the customer at the heart of decision-making. Investing in a CDP enables retailers to exceed customer expectations, drive returns, and thrive amid fierce competition. If you haven’t yet explored CDPs, now is the time to future-proof your retail business with advanced retail system tools—ensuring agility, compliance, and sustained growth. For tailored CDP integration and AI solutions, explore TechOTD’s expertise today. FAQ What is a CDP and how does it differ from a CRM? A CDP unifies customer data from all sources for 360° analysis and activation, while a CRM

Business

Understanding Business Intelligence and Its Importance for Your Organization

Introduction In today’s fast-paced, data-driven business environment, Business Intelligence (BI) has become an indispensable asset for organizations seeking to transform raw data into actionable insights. Business Intelligence empowers companies to make informed decisions, optimize operations, and gain a competitive edge. This blog delves into why BI is crucial for your organization, exploring its benefits, applications, and impact on strategic growth. What Is Business Intelligence? Business Intelligence refers to the technologies, processes, and practices that collect and analyze data to provide meaningful insights. BI systems gather data from various sources, process it, and present it visually through dashboards, reports, and analytics tools, enabling leaders to understand performance, identify trends, and drive better decisions. Why Is Business Intelligence Important for Your Organization? 1. Enhanced Decision-Making with Data-Driven Insights BI replaces guesswork with factual data, enabling executives and teams to make timely, evidence-based decisions. This reduces risks and improves strategic and operational outcomes. 2. Improved Operational Efficiency By providing visibility into processes and detecting inefficiencies, BI helps organizations streamline workflows, reduce costs, and boost productivity across departments. 3. Better Customer Understanding and Targeting BI analyzes customer behavior, preferences, and trends to optimize marketing campaigns, personalize customer experiences, and increase retention. 4. Accurate Performance Monitoring and Benchmarking Organizations can track KPIs in real-time, measure progress against goals, and identify areas needing improvement, facilitating continuous performance optimization. 5. Competitive Advantage and Market Adaptability Timely insights into market trends and competitive positioning allow businesses to innovate rapidly, seize opportunities, and mitigate threats. 6. Scalability and Growth Enablement BI solutions support scalable data analysis, enabling organizations to grow without losing control over their business intelligence capabilities. 7. Streamlined Collaboration and Information Sharing Centralized data platforms enhance cross-functional communication, reduce data silos, and empower employees with role-based access to relevant insights. How Business Intelligence Supports Different Business Functions Sales and Marketing: Analyzing conversion rates, revenue trends, and marketing ROI. Finance: Budget tracking, cash flow analysis, and fraud detection. Human Resources: Employee productivity, payroll management, and satisfaction analysis. Supply Chain: Inventory optimization, vendor analytics, and logistics monitoring. Executive Leadership: Real-time performance dashboards for strategic oversight. The Role of Advanced Technologies in BI Artificial Intelligence and Machine Learning: Enhance predictive analytics and automate insights generation. Blockchain: Ensure data authenticity and secure audit trails. Cloud Computing: Facilitate scalable, real-time data access and collaboration. Discover AI-driven BI strategies and blockchain integration at TechOTD AI Services and TechOTD Blockchain Blog. Implementing an Effective Business Intelligence Strategy Assess Business Needs and Goals: Define clear objectives that BI should support. Collect and Integrate Data: Aggregate data from multiple sources ensuring quality. Choose BI Tools and Platforms: Select solutions aligned with organizational size and complexity. Develop Dashboards and Reports: Create actionable visualizations tailored for users. Train Teams and Foster a Data Culture: Empower employees to leverage BI in daily workflows. Monitor, Update and Evolve: Continuously refine BI processes based on feedback and changing needs. Conclusion Business Intelligence is not just a tool but a strategic asset that transforms how organizations operate, compete, and grow. Firms that invest in robust BI systems gain deeper insights, sharper responsiveness, and stronger decision-making capabilities—critical factors in today’s competitive markets.

Scroll to Top